
NS0-158 · Question #51
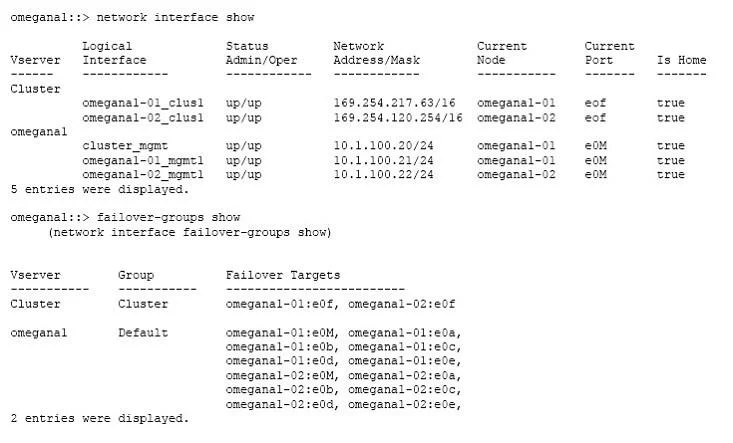
Click the Exhibit button. You have a 2-node NetApp cluster. You perform a storage failover and notice that IP address 10.1.100.21 is unreachable while omegana1-01 is rebooting. After omegana1-01 is…
The correct answer is C. The node management LIFs cannot fail over to other nodes. The IP address 10.1.100.21 was unreachable because it is a node management LIF, and by design, node management LIFs do not fail over to other nodes during a storage failover takeover.
Question
Click the Exhibit button. You have a 2-node NetApp cluster. You perform a storage failover and notice that IP address 10.1.100.21 is unreachable while omegana1-01 is rebooting. After omegana1-01 is back online, the IP address becomes reachable again. However, IP address 10.1.100.20 was still reachable during the reboot. The commands shown in the exhibit were executed before the storage failover. In this scenario, why was IP address 10.1.100.21 unreachable?
Exhibit
Options
- AThe LIF for 10.1.100.21 has an incorrect failover setting.
- BThe failover group for 10.1.100.21 is misconfigured.
- CThe node management LIFs cannot fail over to other nodes.
- DThe Address Resolution Protocol (ARP) cache needs to be cleared on the upstream switch.
How the community answered
(57 responses)- A9% (5)
- B5% (3)
- C84% (48)
- D2% (1)
Why each option
The IP address 10.1.100.21 was unreachable because it is a node management LIF, and by design, node management LIFs do not fail over to other nodes during a storage failover takeover.
If 10.1.100.21 is a node management LIF, its default failover setting is typically to not migrate, which is the expected and intended behavior, not an incorrect configuration.
Failover groups are primarily used to define migration targets for data LIFs, not for node management LIFs, which have a distinct, non-migratory failover policy.
Node management LIFs are designed to provide access to a specific node for management purposes and, by default, do not fail over to a partner node during a storage failover.
An ARP cache issue would likely affect both LIFs or be a symptom of a broader network problem, not the specific differential behavior observed where one LIF failed over and another did not.
Concept tested: NetApp ONTAP Node Management LIF Failover Policy
Source: https://docs.netapp.com/ontap-9/index.jsp?topic=%2Fcom.netapp.doc.dot-cm-concepts%2FGUID-F775799C-438B-450C-BFD0-3B1B1C81FB28.html
Topics
Community Discussion
No community discussion yet for this question.