
DP-100 · Question #55
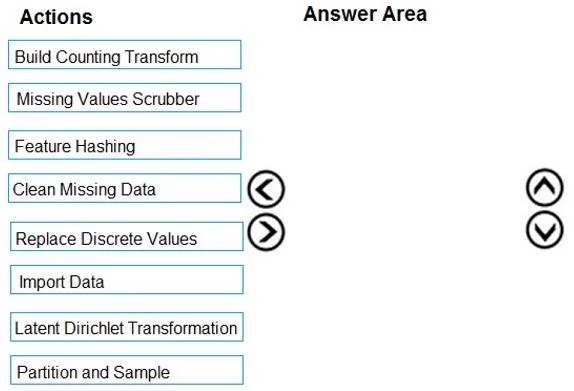
Drag and Drop Question You are creating an experiment by using Azure Machine Learning Studio. You must divide the data into four subsets for evaluation. There is a high degree of missing values in…
The correct answer is Import Data; Clean Missing Data; Partition and Sample. To prepare data for an Azure Machine Learning experiment, data must first be imported, then cleaned to handle missing values, and finally partitioned to create subsets for evaluation.
Question
Exhibit
Answer Area
Drag items
Correct arrangement
- Import Data
- Clean Missing Data
- Partition and Sample
Explanation
To prepare data for an Azure Machine Learning experiment, data must first be imported, then cleaned to handle missing values, and finally partitioned to create subsets for evaluation.
Approach. The correct interaction is to drag the 'Import Data', 'Clean Missing Data', and 'Partition and Sample' modules from the 'Actions' list to the 'Answer Area' and arrange them in that sequence. This sequence is correct because:
- Import Data: Any machine learning experiment must begin with data ingestion. The 'Import Data' module is used to bring datasets into Azure Machine Learning Studio.
- Clean Missing Data: The problem statement explicitly mentions 'a high degree of missing values in the data'. After importing data, the logical next step in data preparation is to handle these missing values. The 'Clean Missing Data' module is designed specifically for this purpose, allowing operations like removing rows, replacing with mean/median/mode, or other imputation methods.
- Partition and Sample: The problem states that the data 'must be divided into four subsets for evaluation'. The 'Partition and Sample' module is used to split a dataset into multiple partitions (e.g., for training, testing, validation) or to sample a portion of the data, directly fulfilling this requirement.
Common mistakes.
- common_mistake. Common mistakes include selecting modules not relevant to the specific problem statement or arranging them in an incorrect order.
- Missing Values Scrubber: While also related to missing values, 'Clean Missing Data' is a more direct and commonly used module for general missing value imputation as indicated by the solution. Choosing 'Missing Values Scrubber' instead of 'Clean Missing Data' might be considered an alternative, but 'Clean Missing Data' is a standard primary choice.
- Build Counting Transform, Feature Hashing, Replace Discrete Values, Latent Dirichlet Transformation: These are feature engineering or transformation techniques that are not directly related to the core requirements of importing data, cleaning missing values, or partitioning the dataset as described in the problem. They might be used later in an experiment but are not the initial preparatory steps required here.
- Incorrect Order: Placing 'Clean Missing Data' before 'Import Data' is incorrect because there's no data to clean yet. Placing 'Partition and Sample' before 'Clean Missing Data' would result in partitioning data that still contains a high degree of missing values, leading to inconsistencies across subsets or problems in subsequent model training/evaluation.
Concept tested. The underlying technical concept being tested is the fundamental workflow of data preparation in Azure Machine Learning Studio, specifically covering data ingestion, handling missing values, and splitting data for experiment evaluation. This demonstrates an understanding of the logical sequence of operations required before training a machine learning model.
Topics
Community Discussion
No community discussion yet for this question.