
DP-100 · Question #286
Drag and Drop Question You previously deployed a model that was trained using a tabular dataset named training- dataset, which is based on a folder of CSV files. Over time, you have collected the…
The correct answer is training-dataset; predictions-dataset. The data drift monitor requires a baseline dataset, which is the original training data, and a target dataset, which is the newly collected inference data matching the baseline schema for feature comparison.
Question
Exhibit
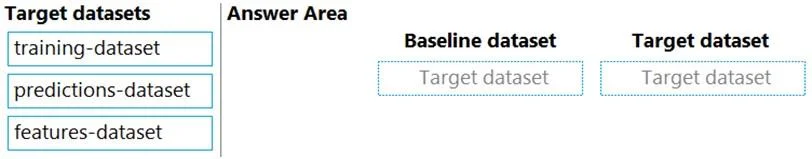
Answer Area
Drag items
Correct arrangement
- training-dataset
- predictions-dataset
Explanation
The data drift monitor requires a baseline dataset, which is the original training data, and a target dataset, which is the newly collected inference data matching the baseline schema for feature comparison.
Approach. To configure a data drift monitor, you must define a baseline dataset and a target dataset. The baseline dataset represents the 'known good' state, which is the data the model was originally trained on. In this scenario, 'training-dataset' is explicitly stated as the dataset used to train the model, making it the correct choice for the Baseline dataset. The target dataset is the new data collected over time, which you want to monitor for drift. The question specifies the need to identify changing trends in the 'feature data'. We have two options for inference data: 'predictions-dataset' (features + predicted label, schema matches training data) and 'features-dataset' (features + timestamp). For data drift monitoring, especially when comparing against a training dataset that likely includes both features and a true label, using 'predictions-dataset' is ideal because its schema 'matches the training data exactly, including the predicted label'. This ensures a direct and consistent comparison of all relevant columns, including features, between the baseline and target. Therefore, drag 'training-dataset' to 'Baseline dataset' and 'predictions-dataset' to 'Target dataset'.
Common mistakes.
- common_mistake. A common mistake would be to use 'features-dataset' for the Target dataset. While 'features-dataset' contains the feature columns, 'predictions-dataset' is explicitly described as having a schema that 'matches the training data exactly, including the predicted label'. When setting up a data drift monitor, having a consistent schema between the baseline and target datasets is crucial for accurate comparison across all features and potentially the label column if it was part of the training data. 'features-dataset' has a timestamp column instead of a label column, making its schema different from the original 'training-dataset', which would complicate a direct, comprehensive drift comparison.
Concept tested. Azure Machine Learning data drift monitoring, specifically understanding the roles of baseline and target datasets for detecting changes in feature distributions over time.
Topics
Community Discussion
No community discussion yet for this question.