
DP-203 · Question #76
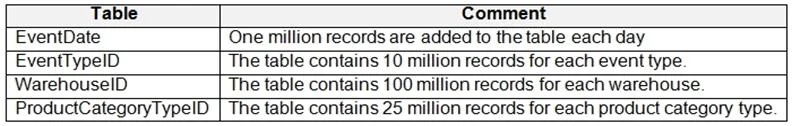
You are designing an inventory updates table in an Azure Synapse Analytics dedicated SQL pool. The table will have a clustered columnstore index and will include the following columns: You identify…
The correct answer is C. WarehouseID. The number of records for each warehouse is big enough for a good partitioning. Note: Table partitions enable you to divide your data into smaller groups of data. In most cases, table partitions are created on a date column. When creating partitions on clustered columnstore…
Question
You are designing an inventory updates table in an Azure Synapse Analytics dedicated SQL pool. The table will have a clustered columnstore index and will include the following columns:
You identify the following usage patterns:
- Analyst will most commonly analyze transactions for a warehouse.
- Queries will summarize by product category type, date, and/or
inventory event type.
- You need to recommend a partition strategy for the table to minimize
query times. On which column should you recommend partitioning the table?
Exhibit
Options
- AProductCategoryTypeID
- BEventDate
- CWarehouseID
- DEventTypeID
How the community answered
(45 responses)- A2% (1)
- B7% (3)
- C80% (36)
- D11% (5)
Explanation
The number of records for each warehouse is big enough for a good partitioning. Note: Table partitions enable you to divide your data into smaller groups of data. In most cases, table partitions are created on a date column. When creating partitions on clustered columnstore tables, it is important to consider how many rows belong to each partition. For optimal compression and performance of clustered columnstore tables, a minimum of 1 million rows per distribution and partition is needed. Before partitions are created, dedicated SQL pool already divides each table into 60 distributed
Topics
Community Discussion
No community discussion yet for this question.