
DP-100 · Question #482
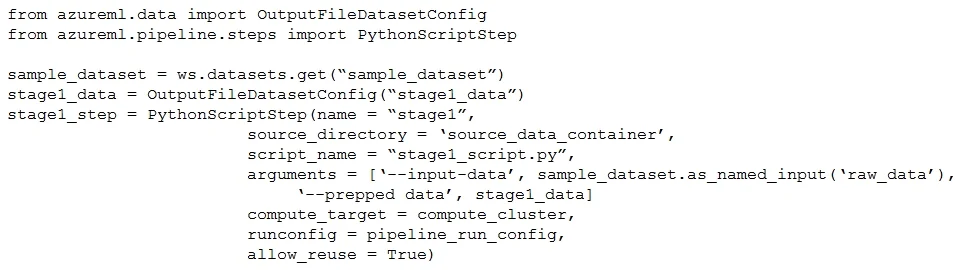
You create an Azure Machine Learning workspace. The workspace contains a dataset named sample_dataset, a compute instance, and a compute cluster. You must create a two-stage pipeline that will…
The correct answer is A. workspaceblobstore datastore. In Azure Machine Learning pipelines, the default datastore for storing pipeline step outputs is the workspaceblobstore, which is backed by the Azure Blob Storage account associated with the Azure ML workspace. When the first pipeline stage writes output data (for example…
Question
Exhibit
Options
- Aworkspaceblobstore datastore
- Bworkspacefilestore datastore
- Ccompute instance
- Dcompute_cluster
How the community answered
(35 responses)- A86% (30)
- B9% (3)
- C3% (1)
- D3% (1)
Explanation
In Azure Machine Learning pipelines, the default datastore for storing pipeline step outputs is the workspaceblobstore, which is backed by the Azure Blob Storage account associated with the Azure ML workspace. When the first pipeline stage writes output data (for example, prepared data stored via OutputDatasetConfig or a similar mechanism), that data is automatically persisted to the workspaceblobstore datastore. The second stage can then read from this location as its input. The workspacefilestore is backed by Azure Files and is typically used for compute instance home directories. Compute instances and compute clusters are ephemeral compute resources-their local storage is not reliably shared between pipeline steps or runs and is not the designated output location.
Topics
Community Discussion
No community discussion yet for this question.